
Design Figma – Frontend System Design
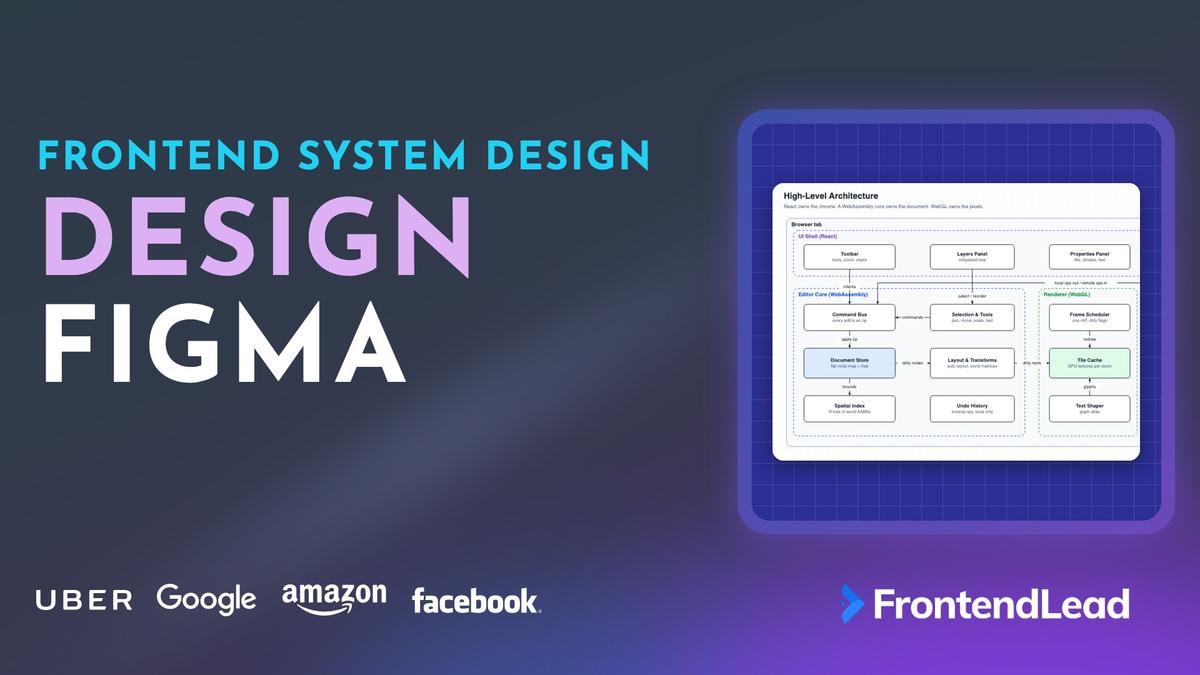
We’ll walk through the frontend system design for Figma: a professional vector design tool that runs in a browser tab, renders files with tens of thousands of layers, and lets a whole team edit the same file at once. You’ll see why the document lives in a WebAssembly core instead of React state, how a tiled WebGL renderer keeps panning smooth, how a click finds the right node among 50,000, and how multiplayer converges without operational transforms.
This is not the whiteboard question. A whiteboard with a few hundred shapes is fine on Canvas 2D. Figma is the version where the interviewer says “assume 50,000 nodes, nested frames, components, and ten people in the file”, and every shortcut you took in the whiteboard answer stops working.
Problem Statement
Design the frontend for a collaborative vector design tool like Figma.
Requirements:
- An infinite canvas with smooth pan and zoom, from 2% to 25,600%
- Frames, groups, vector paths, text, and images, nested to any depth
- Select, move, resize, and edit vector points with precise hit testing
- Components and instances with overrides
- Real-time multiplayer: live cursors, selections, and edits
- Large files (tens of thousands of nodes) that open fast and stay at 60fps
Describe the client architecture, the document model, the renderer, and the sync protocol.
Interviewers are checking three things. Can you separate the document from the renderer? Can you explain how pixels get to the screen without redrawing the world every frame? And can you describe a sync model that converges, rather than hand-waving “we use CRDTs”?
Clarifying Questions
| # | Question | Interviewer’s Answer |
|---|---|---|
| 1 | Vector design (Figma) or raster painting (Photoshop)? | Vector. Images are just fills. |
| 2 | How big is a large file? | 50,000+ nodes, hundreds of images, many pages. |
| 3 | How many concurrent editors per file? | Usually 1–10. Up to a few hundred viewers in a big review. |
| 4 | Do we need prototyping, plugins, or Dev Mode? | Out of scope. Mention plugins in security if you have time. |
| 5 | Offline editing? | Keep working through a short disconnect. Full offline is not required. |
| 6 | Which browsers and devices? | Desktop Chrome, Safari, Firefox, Edge. Tablets are view-mostly. |
Question 2 decides the renderer. Question 3 decides the sync model: a handful of editors on a tree of objects is a very different problem from 100 people typing into one paragraph. Question 5 tells you that a queue of pending ops is enough. You don’t need a full local-first database.
Requirements
Functional
- Pan with space+drag, trackpad, or middle mouse. Zoom toward the cursor with pinch, ctrl+wheel, or keyboard.
- Create frames, rectangles, ellipses, vector paths (pen tool), text, and image fills.
- Select by click, shift-click, and marquee. Move, resize, rotate, and edit vector points.
- Layers panel with nesting, reorder, rename, lock, and hide.
- Components and instances. Editing the main component updates every instance that has not overridden that property.
- Multiplayer: live cursors, live selections, and edits that appear within a few hundred milliseconds.
- Undo and redo that only undo your changes.
- Version history and copy/paste between files.
Non-Functional
- 60fps while panning, zooming, and dragging, even in a 50,000-node file.
- Time to first render of a large file under a few seconds, with the visible page first.
- Memory bounded: GPU textures and decoded images have a budget and an eviction policy.
- No lost work: edits made during a short network drop sync when the socket comes back.
- Keyboard and screen reader access to the chrome (toolbar, layers, properties).
60fps gives you a 16.7ms budget for input, document updates, and painting. The whole design follows from that number. Anything that walks every node, re-renders a React tree, or uploads a full-screen texture on each pointer event will blow it.
Napkin Math
| Metric | Estimate | Calculation | So what? |
|---|---|---|---|
| Document memory | ~50–100 MB | 50,000 nodes × 1–2 KB of properties | Plain JS objects add GC pauses. A packed Wasm heap does not. |
| Viewport in device pixels | ~14.7 M px | 2560 × 1440 CSS px at DPR 2 = 5120 × 2880 | Repainting all of it every frame is wasteful. |
| Tiles to cover the viewport | ~240 | (5120 / 256) × (2880 / 256) ≈ 20 × 12 | Most frames touch zero or a handful of them. |
| GPU memory for one screen of tiles | ~60 MB | 240 × 256 × 256 × 4 bytes | Add a prefetch ring and zoom levels, then cap with LRU. |
| Pointer events while dragging | 60–240 / sec | One per display frame, more with coalesced pen events | Input writes data. Only the frame scheduler paints. |
| Multiplayer ops while dragging | ~20 / sec / user | Batch drag ops every 50ms | Ten editors means ~200 small messages a second. Easy for a socket. |
Architecture

The client has four layers, and the most important decision is which one owns the data.
| Layer | Owns | Runs on | Talks to |
|---|---|---|---|
| UI Shell | Toolbar, layers, properties, comments | React, main thread | Reads derived state, sends intents |
| Editor Core | Document, selection, tools, undo, layout | WebAssembly, main thread | Renderer and multiplayer client |
| Renderer | Tiles, GPU buffers, glyph atlas | WebGL (or WebGPU) | Reads the document and dirty rects |
| Network | Socket, pending ops, asset cache | Main thread + IndexedDB | Multiplayer server, CDN, REST API |
Figma itself is built this way. The editor is C++ compiled to WebAssembly, and it draws with its own GPU renderer rather than the DOM. The browser only provides a canvas element and input events. Figma has since started shipping a WebGPU backend, but the architecture is the same: the GPU API is a detail behind the renderer boundary.
“React renders the panels around the canvas. The document lives in a compiled core with a packed memory layout, because 50,000 nodes as JS objects means GC pauses in the middle of a drag.”
You don’t have to say “C++” in the interview. TypeScript with typed arrays and careful allocation works for a smaller version. The senior point is the boundary: the canvas never reads from React, and React never re-renders on pointermove.
Why not SVG or Canvas 2D?
| Renderer | Good at | Breaks at |
|---|---|---|
| SVG / DOM | Free hit testing, accessibility, crisp text | A few thousand nodes: style and layout cost per element |
| Canvas 2D | Simple API, good for a whiteboard | Large scenes: CPU rasterization, no control over caching |
| WebGL / WebGPU | GPU compositing, tiles, blend modes, effects | You build text, hit testing, and anti-aliasing yourself |
The cost of WebGL is that you own everything the browser used to give you for free: text layout, hit testing, anti-aliasing, and accessibility. Say that out loud. It shows you know what you are signing up for.
Data Model

The document is a flat map of nodes keyed by id. The tree is not stored as nested arrays. Each node points to its parent and carries a fractional index string that orders it among its siblings.
type NodeId = `${number}:${number}`; // sessionId:counter, unique without a server round trip

type NodeType = "DOCUMENT" | "CANVAS" | "FRAME" | "GROUP" | "VECTOR" | "TEXT" | "INSTANCE" | "COMPONENT";

type Mat2x3 = readonly [a: number, b: number, c: number, d: number, tx: number, ty: number];

interface Node {
  id: NodeId;
  type: NodeType;
  parentId: NodeId | null;
  index: string;            // fractional index among siblings, e.g. "a0V"
  transform: Mat2x3;        // relative to the parent
  size: { w: number; h: number };
  fills: Paint[];
  strokes: Paint[];
  opacity: number;
  visible: boolean;
  vector?: VectorNetwork;
  text?: TextData;
  componentId?: NodeId;     // INSTANCE only
}

interface VectorNetwork {
  vertices: { x: number; y: number }[];
  segments: { a: number; b: number; ta: [number, number]; tb: [number, number] }[];
  regions: { loops: number[][]; windingRule: "NONZERO" | "EVENODD" }[];
}
Four choices in that model are worth defending.
Flat map, not a nested tree. Every multiplayer op targets (nodeId, property). With a flat map, applying an op is one hash lookup. Moving a node to a new parent is a single property change (parentId), not a splice out of one array and into another.
Client-generated ids. The id is the session id plus a counter. A client can create a node and reference it in the same batch of ops, with no round trip to ask the server for an id.
Fractional indexes for order. To drop a layer between siblings at "a0" and "a1", you generate a key between them. Nobody else’s keys change, so two people reordering different layers never conflict.
The key is just a string that sorts lexicographically. Inserting between "a0" and "a1" yields something like "a0V". Inserting before the first sibling or after the last extends the range in that direction. Use an existing fractional indexing library rather than inventing the alphabet. Two clients can still generate the same key for the same gap at the same moment, so the server breaks ties by node id and keys can be rebalanced in a rare background pass if they grow long.
Vector networks, not paths. An SVG path is an ordered list of commands, so every point has at most two neighbours. Figma’s vector networks are a graph: any vertex can connect to any number of segments, and fills are regions bounded by loops in that graph. That is why you can draw a three-way junction with the pen tool. For the renderer, it means fills are computed from regions, not from path order.
Components are nodes too. An instance stores componentId plus a sparse map of overrides keyed by the path to the overridden child. Resolving an instance means “read the component’s subtree, then apply overrides”. Cache the resolved result and invalidate it when either the component or the overrides change.
Scene Graph and Transforms
Each node stores a transform relative to its parent. The renderer and the hit tester need world transforms. Computing those by walking up to the root on every query is O(depth) per node per frame, so cache them.
The core keeps a world matrix cache keyed by node id. A lookup returns the cached matrix or computes it as the parent’s world matrix times the node’s local transform, then stores it. When a node’s transform, parent, or size changes, the core evicts that node and its whole subtree from the cache. Reads are lazy and memoized, writes are eager invalidations. The trade-off is memory (one six-number matrix per node, trivial at 50,000 nodes) for constant-time reads in the renderer and hit tester.
Moving a frame with 2,000 children invalidates 2,000 cache entries. That is fine: it happens once per frame, not once per child per query. What you must avoid is recomputing it on every hit test.
The camera maps world space to screen space. Zoom toward the cursor by keeping the world point under the pointer fixed.
type Camera = { x: number; y: number; zoom: number }; // x, y = world point at screen (0, 0)
Screen to world is world = camera.xy + screen / zoom. To zoom toward the cursor, convert the pointer to world space before the zoom, clamp the new zoom (roughly 2% to 25,600%), then solve for the camera origin that puts that same world point back under the pointer. The camera is a plain value. Every zoom or pan produces a new camera, which makes it trivial to animate, persist per user, and compare between frames.
Precision matters at 25,600% zoom. Float32 on the GPU loses sub-pixel accuracy far from the origin, so keep world coordinates in Float64 on the CPU and send the GPU positions relative to the tile or viewport origin.
Rendering Deep Dive

The renderer’s job is to do almost nothing on most frames. There are two paths into a frame.
Edit path. An op changes a node. The core marks the node and its ancestors dirty, recomputes world matrices and bounds, and updates the spatial index with both the old and new bounds. The union of old and new bounds is the dirty world rect. Both matter: the old area must be repainted to erase the node, and the new area to draw it.
Camera path. A pan or zoom changes no document data. The renderer reuses every tile it already has and only rasterizes tiles that just scrolled into view.
Tiles

Split world space into fixed tiles (say 256 × 256 device pixels) per zoom level. Each tile is a GPU texture holding the rasterized content of that square. A frame composites the visible tiles as textured quads, then draws overlays (selection boxes, handles, cursors) on top.
- Visible and cached: composite only. This is the common case while panning.
- Visible and dirty: re-rasterize. Only the tiles that intersect the dirty world rect.
- Prefetch ring: tiles just outside the viewport, rasterized when the frame has spare time.
- Off-screen: evicted first when the GPU memory budget is hit (LRU).
Zoom is the tricky case. When you zoom from 100% to 110%, the cached 100% tiles are scaled up and shown slightly blurry for a frame or two while the 110% tiles rasterize. Users accept a brief soft frame. They do not accept a stutter. Snap tile sets to discrete zoom levels (powers of two plus a few steps) so continuous zoom doesn’t create a new tile set for every wheel tick.
Rasterizing a tile
- Query the R-tree for nodes whose world bounds intersect the tile.
- Walk them in paint order (parent before children, siblings by fractional index).
- For each vector: tessellate the fill regions into triangles once, cache the geometry per node, and draw with the tile’s transform. Strokes become triangle strips with joins and caps.
- Blend modes, masks, and effects like drop shadows render into offscreen framebuffers and then composite.
- Text draws from a glyph atlas (see below).
Cache tessellated geometry per node in world-independent space. A drag changes the transform, not the geometry, so moving a complex vector is a uniform update, not a re-tessellation.
Text
Text is the part people forget. WebGL has no text API. You need font loading, shaping (turning a string into positioned glyphs, including ligatures and right-to-left scripts), line breaking, and glyph rasterization.
Ship a shaping engine in WebAssembly (HarfBuzz is the standard choice), load fonts as binary data, and rasterize glyphs into an atlas texture keyed by (font, glyph, size bucket). Each text node becomes a list of quads that sample from the atlas. The same layout code must run everywhere the text is measured, otherwise auto-layout frames size themselves differently from what you draw.
The frame loop
The frame loop is a small scheduler owned by the renderer. It holds two pieces of state: an accumulated dirty world rect and a flag that says a frame is already scheduled.
- Edits call
invalidate(rect), which unions the rect into the pending dirty area and schedules onerequestAnimationFrame. Ten edits in one frame still cost one frame. - Camera changes schedule a frame with no dirty rect, so every cached tile is reused.
- Each frame marks tiles that intersect the dirty rect, rasterizes dirty visible tiles within a fixed time budget (about 8ms), composites all visible tiles, draws overlays, and reschedules itself if work is left over.
The time budget is the important decision. If a big paste dirties 80 tiles, you rasterize what fits in 8ms, composite stale tiles for the rest, and finish over the next few frames. The canvas stays responsive.
Hit Testing and Input
A click has to find the topmost node under the pointer among 50,000. Walking every node in reverse paint order is O(n) per pointer event. At 120 events a second that is millions of checks.
- Screen to world. Invert the camera.
- Broad phase. Query the R-tree for nodes whose world AABB contains the point. Typically 2–10 candidates.
- Narrow phase. Test candidates topmost first: transform the point into the node’s local space, then test fill regions with the winding rule, and strokes within a tolerance of half the stroke width plus a few screen pixels.
- Selection rules. A click selects the topmost child of the current context (the nearest selectable ancestor), not the deepest leaf. Double-click goes one level deeper. Locked and hidden nodes are skipped.
The hit tester owns this. Its input is a screen point and the current camera. Its output is a node id or nothing. It converts the tolerance (about 4 screen pixels) to world units so hit slop feels the same at every zoom, asks the R-tree for candidates in a tiny box around the point, sorts them topmost first, skips hidden and locked nodes, and runs the precise geometry test in local space. The first hit is mapped to its selectable ancestor before it is returned. Because candidates come from the spatial index, cost depends on how many shapes overlap the point, not on document size.
An alternative is GPU picking: render node ids as colors into an offscreen buffer and read back one pixel. It is exact for complex shapes, but readPixels stalls the GPU pipeline. The R-tree plus geometry test is cheaper for clicks and hovers. Mention GPU picking as the fallback, not the default.
Input pipeline
- Listen to
pointerdown,pointermove, andpointerupon the canvas withsetPointerCapture, so a drag that leaves the canvas still finishes. - For the pen tool, read
event.getCoalescedEvents(). Browsers batch high-rate pen input into one event per frame, and the coalesced list gives back the full curve. - Handlers only update the active tool’s transient state and call
invalidate. The tool commits a real op onpointerup(or at 50ms intervals during a drag for multiplayer). - Prevent the browser’s own pinch zoom with a non-passive
wheellistener whenctrlKeyis set (that is how trackpad pinch arrives), and withtouch-action: noneon the canvas.
Multiplayer

This is where most candidates say “CRDTs” and stop. Be more specific. A design file is a tree of objects with properties. It is not a text document. That makes the problem much simpler than Google Docs.
Figma’s published approach, and the one to propose, is a central server that is the authority for each file, with last-writer-wins at the granularity of one property on one node.
- Every edit is an op like
{ id: "7:12", prop: "fills", value: [...] }. - The client applies its op locally right away, then sends it.
- The server assigns a sequence number in arrival order and broadcasts it.
- Two people changing different properties, or different nodes, never conflict.
- Two people changing the same property: the later sequence number wins, on every client.
The subtle part is what a client does with a server op for a property it has an unacked change on. If Marco has set the fill to blue and the server has not acknowledged it yet, and a broadcast arrives saying “fill = red”, Marco’s client ignores it. His blue is going to be sequenced after that red, so blue is the final answer. Applying red would make the fill flicker red and then blue.
The client keeps an unacked map keyed by nodeId.property, storing the latest local client sequence number that touched that property.
- Local edit: apply to the document, record the client sequence for that key, send the op.
- Server echo of our own op: if it matches the latest sequence for that key, clear the entry. An older echo leaves it, because a newer local write is still in flight.
- Remote op: if the key has an unacked local write, drop it. Our pending write is sequenced later and will win. Otherwise apply it.
The failure mode to name is a rejected op. If the server rejects our write, the client clears the key and requests the authoritative value, otherwise the property stays stuck at a value nobody else sees.
Structure changes
Creating and deleting nodes are ops too. Deletion is a tombstone: the node is marked removed so a late op for it is dropped rather than resurrecting it.
Reparenting is a property change on parentId, and it is the one place last-writer-wins is unsafe. If Priya drags frame A into frame B while Marco drags B into A, applying both creates a cycle. The server validates parent changes and rejects any that would make a node its own ancestor. The client that sent the rejected op reverts it.
Undo in multiplayer
Undo must only undo your own changes. When you apply a local op, record its inverse (the property’s previous value) on your undo stack. Undo applies that inverse as a new forward op, which syncs like any other edit. Remote ops never enter your stack, so pressing Cmd+Z never reverts a teammate’s work.
Group the ops from one gesture (a whole drag, a paste) into one undo entry. Nobody wants to press undo 40 times to reverse one move.
Why not a CRDT or OT?
| Approach | Fits a design file? | Why |
|---|---|---|
| Operational Transform | Overkill | Built for character sequences. Object properties need no transforms. |
| Full CRDT (Yjs, Automerge) | Works, with costs | Peer-to-peer convergence you don’t need, plus metadata per field. |
| Server-ordered LWW per property | Yes | Simple, small messages, server can validate (cycles, permissions). |
Text content inside a text node is the exception you should call out. Two people typing in the same text layer at the same time is rare in a design tool, so LWW on the whole string is an acceptable trade-off. If the interviewer pushes, a text CRDT for that one property is the upgrade path.
Presence
Cursors, selections, and viewports are presence, not document state. Send them on the same socket but on a separate channel, throttled to about 20 updates per second, and never persist them. On the receiving side, interpolate cursor positions between updates so they glide instead of jumping. Draw them in the overlay pass, so they never dirty a tile.
API
Two transports. REST for things that are request-response, and one WebSocket per open file for everything live.
// REST
GET  /api/files/:key                 // metadata, permissions, page list, latest checkpoint url
GET  /api/files/:key/pages/:pageId   // a page's nodes (for lazy page loading)
POST /api/images                     // upload bytes, returns { hash }; dedupes by content hash
GET  /api/files/:key/versions        // named versions and autosaves

// WebSocket: wss://mp.example.com/files/:key
type ClientMessage =
  | { type: "join"; sessionId: string; lastSeq: number | null }
  | { type: "ops"; clientSeq: number; ops: Op[] }
  | { type: "presence"; cursor?: Point; selection?: NodeId[]; viewport?: Rect };

type ServerMessage =
  | { type: "snapshot"; seq: number; nodes: EncodedNodes }
  | { type: "ops"; seq: number; origin: string; clientSeq: number; ops: Op[] }
  | { type: "reject"; clientSeq: number; reason: "cycle" | "permission" | "stale" }
  | { type: "presence"; sessionId: string; cursor?: Point; selection?: NodeId[] };
On reconnect, the client sends lastSeq. If the server still has its journal from that point, it replays only the missed ops. Otherwise it sends a fresh snapshot, and the client re-applies its pending ops on top. Pending ops live in IndexedDB so a crash or a refresh during a disconnect does not lose them.
Use a binary encoding for snapshots and ops. JSON for a 50,000-node snapshot is tens of megabytes and slow to parse. Figma encodes with a compact schema-based binary format (Kiwi, written by Figma co-founder Evan Wallace). In an interview, “a schema-based binary format like Protocol Buffers” is enough.
Loading Large Files
- Fetch file metadata and permissions over REST. Show the chrome immediately.
- Fetch the latest checkpoint for the current page from storage. Decode in a worker.
- Open the socket with the checkpoint’s sequence number, so the server sends only the ops after it.
- Render the viewport tiles first. Build the R-tree for the page in the background.
- Load other pages when the user opens them. Figma calls this dynamic page loading.
- Decode images lazily: fetch by content hash when a tile that needs them rasterizes. Use a low-resolution variant when zoomed out.
Instances are the catch with lazy page loading. A component on page 1 can be instantiated on page 7, so loading page 7 must also load the components its instances reference.
Optimizations
| Problem | Technique | Effect |
|---|---|---|
| GC pauses during drag | Document in a Wasm heap or typed arrays | No per-frame allocation |
| Repainting the whole screen | Tiles + dirty rects | Most frames composite only |
| Re-tessellating on move | Cache geometry in local space | A move is a matrix update |
| O(n) hit testing | R-tree broad phase | A few candidates per click |
| Huge layers panel | Virtualized tree, expand on demand | Only visible rows mount |
| Panels re-rendering on drag | Subscribe to selection + throttled props | React updates at ~10Hz, not 120Hz |
| Zoomed-out file with 500 images | Mipmapped image variants by zoom | Decodes 64px thumbnails, not 4K photos |
| Big paste freezes the frame | Raster time budget per frame | Work spreads over several frames |
Move image decoding off the main thread with createImageBitmap in a worker. Decoding a 4K PNG on the main thread can take longer than a whole frame.
Handling Edge Cases
- WebGL context loss. The GPU process can reset (driver update, memory pressure). Listen for
webglcontextlostandwebglcontextrestored, then rebuild textures and buffers from the document. Never treat GPU memory as the source of truth. - Retina and monitor changes. Size the canvas backing store to CSS size ×
devicePixelRatio, and rebuild tiles when the ratio changes (dragging the window to another monitor). - Missing fonts. A teammate used a font you don’t have. Render with a fallback, keep the original font name in the document, and show a “missing fonts” warning instead of silently rewriting their text.
- Deleting what someone else is editing. Their later ops target a tombstone and are dropped. Their client shows the node disappearing and exits the edit mode.
- Long disconnect. If the journal no longer covers
lastSeq, take a snapshot and rebase pending ops on it. Ops on deleted nodes are dropped and the user sees a short notice. - Clipboard. Write both a rich payload (encoded nodes inside
text/html) and a PNG, so pasting into Figma keeps layers and pasting into Slack shows an image.
Accessibility and Security
Accessibility
The canvas is one bitmap to a screen reader. You can’t make every vector point accessible, but you can make the tool usable:
- The layers panel is a real
role="tree"with arrow-key navigation, and it is the accessible way to select nodes. - The properties panel is made of native inputs with labels. Every canvas action (move by 1px, resize, reorder) has a keyboard shortcut.
- Announce selection changes in an
aria-live="polite"region: “Frame ‘Header’ selected, 1440 by 96”. - The canvas element gets a label and keyboard focus. Respect
prefers-reduced-motionfor animated zoom.
Security
- The multiplayer server checks permissions on join and on every op. A viewer’s socket can send presence, not ops.
- Pasted and imported SVG is parsed into nodes, never injected into the DOM. Scripts and external references are dropped.
- Plugins run untrusted code. Figma runs plugin logic in a sandboxed JavaScript VM (QuickJS compiled to WebAssembly) with a narrow API, and plugin UI in a separate iframe.
- Images are fetched by content hash from a CDN with short-lived signed URLs, so a leaked link to a private file’s image expires.
What a Strong Answer Sounds Like
| Topic | Junior answer | Senior answer |
|---|---|---|
| Rendering | “Use canvas” | Tiled GPU renderer, dirty rects, raster budget per frame |
| State | Redux store of shapes | Flat node map in a compiled core, React only for chrome |
| Hit testing | Loop over shapes | R-tree broad phase, local-space narrow phase, selection rules |
| Multiplayer | “Use a CRDT” | Server-ordered LWW per property, unacked rule, cycle checks |
| Undo | Snapshot stack | Inverse ops as new forward ops, only your changes |
Conclusion: How to Design Figma
Start with the boundary: React for the panels, a compiled core for the document, and a GPU renderer that only repaints dirty tiles. Store the document as a flat map of nodes with parent pointers and fractional indexes, so every edit is one (node, property, value) op.
That one decision pays off everywhere. The renderer turns ops into dirty rects. Undo stores inverse ops. Multiplayer sends ops to a server that orders them, and last-writer-wins per property converges without operational transforms. If you can explain the unacked-change rule and the reparenting cycle check, you’ve shown the interviewer you understand how real multiplayer editors work.