
Design VS Code for the Web – Frontend System Design
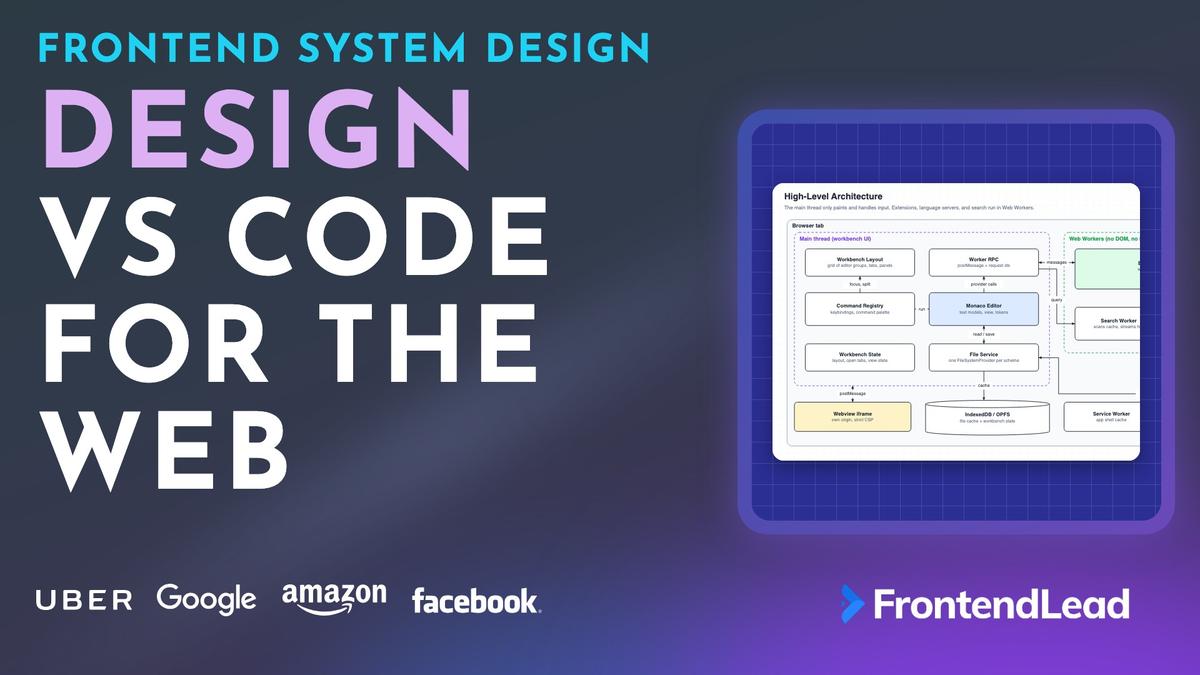
We’ll walk through the frontend system design for a browser-based IDE like vscode.dev or github.dev: open a repository or a local folder in a tab, edit files with syntax highlighting and IntelliSense, search across the project, and install extensions. You’ll see why the text buffer is a piece tree instead of a string, why the editor only builds DOM for the 50 lines you can see, why extensions and language servers live in Web Workers, and how one file system API can sit on top of GitHub, a local disk, and a browser cache.
This is not the coding playground question, which is about running untrusted code in a sandbox. It is also not Google Docs, which is about real-time collaboration. Here the hard parts are a single user’s editor staying under one frame per keystroke on a 100,000-line file, and a plugin system that can’t freeze or compromise the UI.
Problem Statement
Design the frontend for a browser-based code editor like VS Code for the Web.
Requirements:
- Open a GitHub repository or a local folder in a browser tab, with no install
- A file explorer, tabs, split editors, and resizable panels
- Syntax highlighting, completion, hover, and error squiggles for common languages
- Search across every file in the workspace
- A command palette and customizable keybindings
- Extensions that add languages, commands, and custom views
- Files with 100,000+ lines that stay responsive while typing
Describe the client architecture, the text model, rendering, language features, the file system layer, and the extension model.
Interviewers are checking three things. Do you know that a code editor is not a <textarea> with colors on top? Can you keep the main thread free when third-party extensions and language servers want CPU? And can you abstract storage so the editor doesn’t care whether a file came from GitHub or from disk?
Clarifying Questions
| # | Question | Interviewer’s Answer |
|---|---|---|
| 1 | Do we run user code (terminal, debugger, build)? | No. There is no backend compute. Editing, navigation, and language features only. |
| 2 | Where do files come from? | A GitHub repository, or a local folder the user picks. Save back to the same place. |
| 3 | How big is a big repository and a big file? | 20,000 files. Single files up to 100,000 lines, sometimes a 5 MB minified bundle. |
| 4 | Real-time collaboration? | Out of scope. One user per session. |
| 5 | Which languages need rich features? | TypeScript, JavaScript, JSON, CSS, HTML. Others get highlighting only. |
| 6 | Third-party extensions? | Yes, from a marketplace. Assume some are buggy or malicious. |
| 7 | Offline? | The app should load offline and keep unsaved edits. Syncing to GitHub waits for the network. |
Question 1 removes the hardest backend work and tells you every feature runs in the browser. Question 3 decides the text buffer and the renderer. Question 6 decides the process model: if extensions are untrusted and can be slow, they cannot share a thread with the cursor. Question 7 means you need a service worker for the app shell and durable storage for dirty files.
Requirements
Functional
- Open a workspace from a GitHub URL (
/owner/repo) or a local folder. - File explorer tree with create, rename, delete, and drag to move.
- Tabs with preview mode (single click opens a temporary tab), split editors in a grid, and a bottom panel for problems and search results.
- Multi-cursor editing, undo and redo, find and replace in a file, folding, minimap.
- Syntax highlighting for any language with a grammar. Completion, hover, go to definition, and diagnostics for the core languages.
- Workspace search with regex, case, and glob filters, with results that appear as they are found.
- Command palette (Ctrl+Shift+P) that lists every command, and user-defined keybindings.
- Install, enable, and disable extensions without a page reload.
- Restore the layout, open tabs, and cursor positions on the next visit.
Non-Functional
- Keystroke to painted character in under 16ms, even with extensions busy.
- Open a 100,000-line file in under a second and scroll it at 60fps.
- A crashing or looping extension never freezes typing.
- No lost work: unsaved edits survive a tab crash, a refresh, and a network drop.
- Full keyboard operation and screen reader support.
- Extensions cannot read tokens or files outside what the API grants them.
The 16ms number is the whole design. Every keystroke must update the buffer, re-tokenize at least one line, and repaint, inside one frame. Anything that waits on a worker, a language server, or the network has to happen after the character is already on screen.
Napkin Math
| Metric | Estimate | Calculation | So what? |
|---|---|---|---|
| Large file size | ~4 MB of text | 100,000 lines × 40 chars | Copying the whole string per keystroke is wasted work and GC churn. |
| Token memory | ~6.4 MB | 100,000 lines × 8 tokens × 8 bytes (two Uint32 per token) | Store tokens in typed arrays, not objects. |
| DOM if every line rendered | ~900,000 nodes | 100,000 lines × (1 div + 8 spans) | Impossible. Render only visible lines. |
| DOM when virtualized | ~540 nodes | (1,000 px / 20 px + 10 overscan) × 9 | Layout cost is constant, regardless of file size. |
| Keystroke budget | 16.7 ms | 1,000 ms / 60 frames | Buffer edit and one-line re-tokenize must take ~1 ms or less. |
| Workers | 4–6 | Extension host + 2–3 language servers + search | Each has its own heap. Spawn language servers lazily. |
| GitHub API budget | 5,000 requests / hour | Authenticated REST rate limit | Fetch the tree once, blobs on demand. Never one request per file at startup. |
Architecture

Desktop VS Code is a multi-process app: an Electron renderer for the UI, a separate Node.js extension host process, and language servers as more processes. The web version keeps the same split and translates processes into the browser’s unit of isolation, the Web Worker.
| Layer | Owns | Runs on | Talks to |
|---|---|---|---|
| Workbench | Layout, tabs, explorer, palette, panels | Main thread | Editor, command registry, state storage |
| Editor (Monaco) | Text models, cursors, tokens, view | Main thread | Workbench, Worker RPC |
| Extension host | Every extension’s code, the vscode API |
Dedicated Web Worker | Main thread by RPC, network |
| Language servers | Parsing, type checking, completion | One worker per language | Extension host over JSON-RPC |
| File service | URIs, providers, caching, watching | Main thread (providers can be remote) | GitHub, local disk, OPFS |
| Service worker | App shell cache | Service worker | App CDN |
The rule is simple: the main thread only does work that must touch the DOM or must finish within the current frame. Everything else is a message away.
“The main thread owns input and painting. Extensions run in a worker behind an RPC boundary, so an extension stuck in a loop delays its own completions but never my cursor.”
Why extensions must not run on the UI thread
JavaScript on one thread is cooperative. If an extension runs a 300ms synchronous loop on the main thread, input events queue for 300ms and the editor freezes. You can’t preempt it, and you can’t time it out.
A worker fixes all three problems. It has its own event loop, so a busy extension host only delays its own replies. The main thread can measure how long a request has been pending and show “Extension host is unresponsive”. And if it is truly stuck, worker.terminate() kills it and you start a fresh one. That is how you restart an extension host.
The cost is that every interaction is asynchronous. An extension can’t synchronously read the DOM or the cursor. It gets a snapshot of the document that the main thread keeps in sync by sending change events, and it answers questions like “what completions exist at line 12, column 8?” with a promise.
Message passing
postMessage copies data with the structured clone algorithm. That is fine for small messages and expensive for big ones: sending a 4 MB file to a worker clones 4 MB. Three techniques keep the boundary cheap:
- Send deltas, not documents. After the initial open, the worker only receives edits (range plus inserted text).
- Transfer, don’t copy. Pass an
ArrayBufferin the transfer list and ownership moves with no copy. File bytes read from the network go to the search worker this way. - Direct channels. A
MessageChannelgives two workers a port to each other, so the extension host and a language server talk without relaying through the main thread.
type RpcMessage =
  | { kind: "req"; id: number; method: string; params: unknown }
  | { kind: "cancel"; id: number }
  | { kind: "res"; id: number; result?: unknown; error?: { code: number; message: string } };
A small RPC layer wraps every worker and port with that protocol. The caller side keeps a counter for ids and a map of pending requests. request(method, params, signal) returns a promise and posts a req. A res resolves or rejects the matching entry, and a response with no pending entry (already cancelled) is ignored. If the caller’s AbortSignal fires first, the entry is removed, a cancel is posted so the worker can stop, and the promise rejects with an AbortError. The same layer runs on both sides of every boundary, so the main thread, extension host, and language servers all share one cancellation story.
Cancellation is part of the protocol from day one. Code intelligence requests go stale the moment the user types again, and a stale answer is worse than no answer.
Data Model

The key split is between the text model (one per file) and the view state (one per editor). Open the same file in two split editors and both editors share one model, so an edit in the left pane appears in the right pane instantly, but each pane keeps its own cursor and scroll position.
type Uri = string; // "github://owner/repo/src/app.ts", "file:///Users/me/proj/a.ts"

interface TextModel {
  readonly uri: Uri;
  languageId: string;
  versionId: number;         // increments on every edit
  savedVersionId: number;    // dirty when versionId !== savedVersionId
  readonly buffer: PieceTree;
  readonly tokens: Uint32Array[];   // per line: [endOffset, metadata, endOffset, metadata, ...]
  readonly decorations: IntervalTree<Decoration>;
  eol: "n" | "rn";
}

interface Decoration {
  readonly id: string;
  range: Range;              // moves when text is inserted before it
  className: string;         // squiggle, highlight, breakpoint glyph
  owner: string;
}

interface EditorViewState {
  modelUri: Uri;
  selections: Selection[];   // more than one means multi-cursor
  scrollTop: number;
  folded: Range[];
}

interface ExtensionManifest {
  publisher: string;
  name: string;
  browser?: string;          // web entry point; extensions without it cannot run on the web
  activationEvents: string[];// "onLanguage:python", "onCommand:foo.run"
  contributes: { commands?: { command: string; title: string }[]; languages?: unknown[]; grammars?: unknown[] };
  capabilities?: { untrustedWorkspaces?: { supported: boolean | "limited" } };
}
Three choices in that model are worth defending.
A version number on every model. Every message to a language server carries versionId. When diagnostics come back for version 41 and the model is at 43, you know the ranges may be off. You can map them through the edits since 41 or wait for the next publish.
Decorations in an interval tree. A large file can have thousands of decorations: squiggles, search highlights, git change markers. The renderer asks “which decorations overlap lines 2,401 to 2,450?”, and an interval tree answers that in O(log n + k). Monaco stores decorations this way, and edits shift the stored ranges instead of recomputing every one.
Activation events in the manifest. The workbench reads manifests at startup and loads no extension code. A Python extension activates the first time a Python file opens. That keeps startup cost proportional to what you use, not what you installed.
The Text Buffer: Piece Tree

The obvious buffer is a single string. Inserting one character in the middle of a 4 MB string creates a new 4 MB string, every keystroke. The next obvious buffer is an array of lines. Edits inside a line are cheap, but you pay a string object and an array slot per line, loading a file means splitting all of it, and pasting 10,000 lines splices a huge array.
| Representation | Insert | Offset to line | Memory overhead |
|---|---|---|---|
| One string | O(n) copy | O(n) scan | Lowest, but churns on every edit |
| Array of lines | O(line) plus O(lines) for multi-line paste | O(1) by index | One object per line |
| Rope | O(log n) | O(log n) with line counts | Many small leaf strings |
| Piece tree | O(log n) pieces | O(log n) with line feed counts | Original chunks untouched, one append-only add buffer |
VS Code replaced its line array with a piece tree in 2018, and the VS Code blog post on the text buffer reimplementation explains why: memory for files with millions of lines and load time. The idea comes from the classic piece table.
- The original buffer holds the file as loaded. It is never modified. A large file arrives as several chunks (for example 64 KB each), and each chunk becomes its own read-only buffer, so loading never splits or copies text.
- The add buffer holds everything you type, appended at the end. It only grows.
- A piece says “the next length characters come from buffer b at offset start”. The document is the pieces read in order.
- The pieces live in a red-black tree. Each node caches the total length (
size_left) and the number of line feeds (lf_left) in its left subtree. That turns “which piece contains offset 3,000,000?” and “where does line 52,000 start?” into O(log n) walks.
Each tree node holds one piece (buffer index, start offset, length, and its line feed count) plus the two cached subtree totals. Finding the piece at a document offset is a single walk from the root: if the offset is inside the left subtree’s size, go left. If it falls inside this node’s piece, stop and return the offset within the piece. Otherwise subtract the left size and the piece length and go right. Finding a line start works the same way using line feed counts.
An insert appends the text to the add buffer, finds the piece at the offset, splits it into a left and right half, and inserts a new piece between them. Then it rebalances and updates sizeLeft and lfLeft along the path to the root. A delete trims or removes pieces. Neither touches the original text.
Two refinements matter in practice. First, typing is mostly sequential, so if the new text goes right after the last piece and that piece ends at the end of the add buffer, you just extend the piece. Typing a whole word creates one piece, not five. Second, each buffer stores the offsets of its line starts once, so counting line feeds inside a piece is a binary search, not a scan.
Undo also gets cheaper. An undo entry stores the inverse edit (range and text), not a snapshot of the file. And because the original buffer never changes, “revert file” is just rebuilding the tree with one piece per original chunk.
Rendering and Tokenization

Virtualized line rendering
The editor is a scroll container whose height is lineCount × lineHeight, but it only creates DOM for the lines in the viewport plus a few lines of overscan. On scroll, it computes the new range, reuses the line elements it already has, and rewrites only lines whose content or tokens changed.
The range is plain arithmetic. With scrollTop at 48,000px, a 1,000px viewport, and 20px lines, the first visible line is floor(48,000 / 20) + 1 = 2,401 and the last is ceil(49,000 / 20) = 2,450. Add five lines of overscan on each side and you render 60 lines, whether the file has 500 lines or 500,000.
Word wrap and folding break the simple division. A folded region of 500 lines takes zero height, and a wrapped line takes several rows. The fix is a view model between the text model and the DOM: it maps model lines to view lines and keeps a prefix sum of view line counts, so “which model line is at pixel 48,000?” stays a binary search.
Each visible line becomes one div with one span per token, and the class name on each span encodes the token’s color and font style. Monaco builds each line’s markup with a string builder and writes it in one go, which is faster than creating thousands of elements one by one. Because the markup is a string, the text must be HTML-escaped, or a file containing <img onerror> becomes an XSS hole.
Cursors, selections, and squiggles render in separate layers on top of the text. Moving the cursor repaints a 2px element, not the line. Long lines are capped too: Monaco stops rendering a line after a configurable number of characters (editor.stopRenderingLineAfter), which is what keeps a 5 MB single-line minified file from building a 5 MB DOM text node.
Tokenization
Highlighting is a tokenizer that turns each line into a list of (endOffset, scope) pairs. There are two common grammar formats:
- TextMate grammars: JSON or plist files of regular expressions with begin/end rules and nested scopes. VS Code uses them for highlighting, with the Oniguruma regex engine compiled to WebAssembly because the grammars rely on regex features JavaScript’s engine lacks.
- Monarch: Monaco’s own declarative tokenizer, written as a JavaScript object of states and regex rules. Lighter, runs on the built-in regex engine, and is the default when you embed standalone Monaco.
Both share one property that makes incremental re-tokenization work: tokenizing a line takes a start state and returns tokens plus an end state. The state captures things like “inside a block comment” or “inside a template string”. Line n starts with the end state of line n – 1.
So an edit on line 120 invalidates line 120, re-tokenizes it, and compares the new end state with the old one. If they match, every line below is still correct and you stop. If you just typed /*, the end state changes to “in comment”, and re-tokenization continues down the file.
The tokenizer contract is one method: tokenizeLine(text, startState) returns packed tokens (a Uint32Array of end offsets and metadata) and an end state that can be compared for equality. The model stores tokens and end states per line.
The tokenization scheduler re-tokenizes from the edited line using the previous line’s end state. After each line it compares the new end state with the stored one. A match means everything below is still valid, so it stops. A mismatch means it keeps going. It also checks a time budget after each line, and when the budget runs out it returns the next line to resume from in a later slice.
The budget is what protects typing. Tokenize the edited line synchronously so the keystroke paints with correct colors, tokenize the visible lines next, and spread the rest of the file across small slices between frames. Lines that haven’t been tokenized yet render as plain text for a moment. Moving the whole tokenizer to a worker is a common approach for big files, because TextMate tokenization of a long file can take seconds of CPU.
Semantic highlighting from the language server (for example, coloring a variable differently from a parameter) arrives later as a second layer of tokens. It refines the TextMate colors, it never blocks them.
Language Features with LSP

The Language Server Protocol (LSP) separates the editor from language intelligence. The server speaks JSON-RPC 2.0: requests have an id and expect a response (textDocument/completion, textDocument/hover, textDocument/definition), and notifications have no id and get no response (textDocument/didChange, textDocument/publishDiagnostics).
On desktop, a language server is a separate process talking over stdio. In the browser, it is a worker built for the web, talking over postMessage. The language client lives in the extension that owns the language, inside the extension host, and the main thread only sees provider results.
Keeping the server in sync
The server keeps its own copy of every open document. On open it receives the full text once with didOpen. After that, if the server declared incremental sync (TextDocumentSyncKind.Incremental), each edit sends only the changed range and the new text.
// Notification: no id, no response
const didChange = {
  jsonrpc: "2.0",
  method: "textDocument/didChange",
  params: {
    textDocument: { uri: "github://acme/web/src/app.ts", version: 42 },
    contentChanges: [
      { range: { start: { line: 119, character: 14 }, end: { line: 119, character: 14 } }, text: "." },
    ],
  },
};

// Request: has an id, expects a response or an error
const completion = {
  jsonrpc: "2.0",
  id: 17,
  method: "textDocument/completion",
  params: {
    textDocument: { uri: "github://acme/web/src/app.ts" },
    position: { line: 119, character: 15 },
    context: { triggerKind: 2, triggerCharacter: "." },   // 2 = TriggerCharacter
  },
};

// Cancellation is a notification that names the request
const cancel = { jsonrpc: "2.0", method: "$/cancelRequest", params: { id: 17 } };
LSP positions are zero-based lines and character offsets counted in UTF-16 code units by default. Monaco is one-based. Convert at exactly one place, the language client, or every emoji and every off-by-one becomes a bug report.
Debouncing and cancellation
- didChange is never debounced. The server must see every edit in order, or its copy of the document diverges. You can batch several edits from one frame into one notification with multiple
contentChanges. - Diagnostics are debounced on the server. Type checking a big file on every keystroke wastes CPU. The server waits until typing pauses (a few hundred milliseconds is typical), checks, and pushes
publishDiagnosticswith the version it checked. - Completion and hover are cancelled, not debounced. Completion must feel instant on
., so it fires right away. If the user keeps typing before it returns, the client sends$/cancelRequestand the server answers with error code-32800(RequestCancelled). Once a list has arrived, Monaco filters it by the typed prefix and only asks again when the server marked itisIncomplete. In the diagram, request 17 was still in flight, so there was nothing to filter and the client asked again at the new position. - Hover waits for the pointer to rest. A short delay before sending the request avoids a request for every token the mouse crosses.
Diagnostics become markers keyed by (uri, owner). A new publish from the TypeScript server replaces the old TypeScript markers for that file and leaves the ESLint markers alone. Markers become squiggle decorations in the editor and rows in the Problems panel.
Virtual File System
The editor never calls fetch or the File System Access API directly. It asks the file service for a URI, and the file service routes by scheme to a provider. VS Code exposes this to extensions as the FileSystemProvider API, which is how github.dev serves repository files from an extension (GitHub Repositories) rather than from core code. This design uses a github:// scheme for the same idea.
type FileType = "file" | "directory";

interface FileStat {
  type: FileType;
  size: number;
  mtime: number;
  etag: string;            // git blob sha for GitHub, lastModified for local files
}

interface FileSystemProvider {
  stat(uri: Uri): Promise<FileStat>;
  readDirectory(uri: Uri): Promise<[name: string, type: FileType][]>;
  readFile(uri: Uri): Promise<Uint8Array>;
  writeFile(uri: Uri, content: Uint8Array, opts: { create: boolean; overwrite: boolean; etag?: string }): Promise<void>;
  delete(uri: Uri, opts: { recursive: boolean }): Promise<void>;
  rename(from: Uri, to: Uri, opts: { overwrite: boolean }): Promise<void>;
  watch?(uri: Uri, onChange: (uri: Uri) => void): () => void;
}
The file service holds a registry from scheme to provider. Routing reads the scheme from the URI and looks it up. An unknown scheme is a hard error, not a silent fallback to another provider, because writing a github:// file to local storage by accident is data loss.
| Provider | Read | Write | Watch |
|---|---|---|---|
github:// |
Tree once, blobs on demand | Staged locally, committed as a batch | Poll the branch head |
file:// (local) |
FileSystemFileHandle.getFile() |
createWritable() |
Compare lastModified on focus |
| Cache (OPFS / IndexedDB) | Instant, offline | Dirty copies and backups | Not needed |
GitHub
Opening /acme/web makes one call to the Git Trees API with recursive=1, which returns every path, type, and blob sha in the repository. That powers the explorer and file quick-open with no further requests. GitHub caps a recursive tree response at 100,000 entries and 7 MB and sets truncated: true beyond that, so huge monorepos fall back to fetching directories as they expand.
File content is fetched by blob sha when a file opens and cached in OPFS keyed by that sha. Because blobs are content-addressed, a cached entry never goes stale: a changed file has a new sha.
Saving does not write to GitHub immediately. Edits are kept as local changes, the Source Control view lists them, and a commit sends all of them at once: create blobs, create a tree on top of the base tree, create a commit, then move the branch ref. If the branch moved since you opened it, the ref update fails and you show a conflict instead of overwriting someone’s push.
Local folders
In Chromium browsers, window.showDirectoryPicker({ mode: "readwrite" }) returns a FileSystemDirectoryHandle after a user gesture. You walk it with handle.values(), read with getFile(), and write through createWritable(), which writes to a temporary file and swaps it in on close().
Handles are structured-cloneable, so you store the directory handle in IndexedDB and get it back on the next visit. The permission does not come back with it. After a reload, queryPermission() usually returns "prompt", and requestPermission() only works inside a user gesture. So the restore flow is: read the handle, show a “Reopen folder” button, and request permission on click.
There is no file watcher for local handles, so detect outside changes by comparing lastModified when the tab regains focus. Firefox and Safari don’t ship showDirectoryPicker. Fall back to <input type="file" webkitdirectory> for a read-only import, or to an in-browser workspace stored in OPFS.
Cache and storage
The Origin Private File System (navigator.storage.getDirectory()) is the right home for file contents: it is fast, private to the origin, and in a worker createSyncAccessHandle() gives synchronous reads and writes. IndexedDB holds structured state: workbench layout, view states, file handles, and backups of dirty files. Call navigator.storage.persist() so the browser doesn’t evict unsaved work under storage pressure.
Workspace Search
Desktop VS Code searches with ripgrep, a native binary. There is no ripgrep in a browser tab, and no file system to point it at. Search has two phases: get the bytes, then scan them off the main thread.
- Get content. For a local folder, read files from the handles. For GitHub, fetching 20,000 blobs one at a time would burn four hours of rate limit. Download the repository archive once (
GET /repos/{owner}/{repo}/tarball/{ref}), decompress it withDecompressionStream("gzip"), and unpack the tar into OPFS in a worker. - Filter paths first. Apply include and exclude globs and
.gitignorebefore reading a byte. Skip binary files by checking the first few KB for NUL bytes. - Scan in a worker. Compile the query to a
RegExponce, scan each file, and collect line numbers and match ranges. - Stream results. Post batches every 50ms or every 100 matches, whichever comes first. The panel renders the first results while the scan continues.
- Cap and cancel. Stop at a result limit (say 10,000 matches) and tell the user. A new query aborts the old one.
The search worker receives a query (id, pattern, regex flag, case flag, and the filtered file list) and streams back matches as { path, line, start, end, preview }, with the preview capped at about 200 characters.
- A literal query is escaped before it becomes a
RegExp, so searching fora.bdoesn’t matchaxb. - Before each file, the worker checks that its query is still the active one. A newer query or an explicit cancel makes it return immediately.
- Matches are flushed on the batch rules above, and a final message carries
done: trueso the panel can stop its spinner.
A user-supplied regex can backtrack catastrophically. Because it runs in a worker, the UI stays fine, and the main thread can terminate the worker if a search exceeds a time limit. The worker also yields between files, because each file read is asynchronous, so a cancel message is processed promptly.
Commands, Keybindings, and Layout
Command registry
Every action in the IDE is a command with a string id: menus, toolbar buttons, keybindings, the palette, and extensions all call the same registry. That is why the palette can list everything, and why a user can rebind any action.
type ContextKeys = Readonly<Record<string, boolean | string>>;

interface Command {
  id: string;                          // "editor.action.formatDocument"
  title: string;                       // shown in the palette
  run(...args: unknown[]): unknown | Promise<unknown>;
}

interface Keybinding {
  key: string;                         // "ctrl+shift+i", or a chord "ctrl+k ctrl+c"
  command: string;
  when?: (ctx: ContextKeys) => boolean;    // parsed from "editorTextFocus && !editorReadonly"
}
The registry is a map from command id to command, plus an ordered list of keybindings with user bindings appended last. Resolving a key walks the list from the end and returns the first binding whose key matches and whose when clause is true for the current context. Walking from the end is what lets a user override a default without deleting it.
Context keys (editorTextFocus, resourceLangId == python, sideBarVisible) are what make one key do different things in different places. Tab indents in the editor and moves focus in a dialog. Extensions contribute commands in their manifest, so the palette can show them before the extension activates, and running one triggers onCommand activation.
Normalize keys from KeyboardEvent.code plus modifiers, and map Cmd to Ctrl on macOS. Some shortcuts belong to the browser: Ctrl+W, Ctrl+T, and Ctrl+N are not delivered to a page in a normal tab. The Keyboard Lock API (navigator.keyboard.lock()) only works in fullscreen, so ship alternative defaults for those actions in the browser build.
Layout
The workbench is a fixed frame (activity bar, side bar, editor area, panel, status bar) around an editor area that is a grid of editor groups. The grid is a tree: each node is a horizontal or vertical split with child sizes, and each leaf is a group of tabs. Splitting right turns a leaf into a split with two leaves. Dragging a sash resizes two siblings and nothing else.
- Resize with pointer events and
setPointerCaptureon the sash, and apply sizes insiderequestAnimationFrame. - Editors measure their container with
ResizeObserverand re-layout once per frame, not once per pointer event. - Hidden tabs keep their text model but destroy their DOM. Only the active tab in each group has a live editor view.
- Serialize the grid, open editors, and each editor’s view state to IndexedDB, debounced on change and flushed on
visibilitychangeto hidden.beforeunloadis not reliable on mobile and is skipped when a tab is discarded.
Extension Sandboxing
A web extension declares a browser entry point in its package.json. That bundle runs in the web worker extension host, which means no Node.js APIs: no fs, no child_process, no net. An extension that needs the file system uses vscode.workspace.fs, which goes through the file service and its providers. Extensions that only have a Node main entry point cannot run on the web, and the Extensions view marks them as unavailable.
- Worker isolation. The extension host has no DOM. It can’t read the editor’s markup, inject scripts into the workbench, or block its event loop.
- Origin isolation. A common hardening step is to start the extension host worker from a sandboxed iframe on a separate origin. Then extension code can’t read the workbench origin’s IndexedDB, cookies, or storage, even though it shares the tab.
- Webviews. Extensions that need custom UI (a Markdown preview, a diagram editor) get a webview: an iframe on its own origin with a strict Content Security Policy. It talks to its extension only through
postMessage, relayed by the main thread. It can’t touch the workbench DOM. - CSP on the workbench. A strict policy (
script-srclimited to the app’s own origin and the extension CDN, nounsafe-evalwhere possible) means an XSS bug in a file preview can’t load arbitrary scripts. - Activation on demand. Extensions load only when an activation event fires. That limits both startup cost and how much untrusted code runs at all.
Isolation is not permission. An extension that runs at all can call any API it was given, including reading every file in the workspace through vscode.workspace.fs. The real control is what you let run, which is the next section.
State and Data Flow
Follow one keystroke end to end:
- The browser delivers
inputto the hidden<textarea>that holds focus. Monaco reads the inserted text, clears the textarea, and turns it into an edit at every cursor. - The edit applies to the piece tree,
versionIdincrements, decorations shift, and the edited line is re-tokenized synchronously. - The view repaints the changed line and the cursor layer in the next animation frame. The user sees the character. This is the only synchronous part.
- The model change event is sent to the extension host, which updates its document copy and forwards
didChangeto the language server. - Providers run asynchronously: completion if a trigger character was typed, diagnostics when typing pauses. Results carry a version, and stale ones are dropped or mapped.
- The model is now dirty (
versionId !== savedVersionId). A debounced backup writes the dirty content to IndexedDB, so a crash doesn’t lose it. - On save, the file service writes through the provider. Local folders write in place. GitHub saves stage the change until commit.
The data flow is one-directional: input becomes an edit, the model is the source of truth, and the view, the workers, and storage all derive from model change events. No component writes to the view directly, which is what keeps two split editors and the language server consistent.
API
There is no custom backend for editing. The client calls GitHub’s API, the extension marketplace, and the app CDN, and everything live happens over worker messages.
// GitHub REST (all with Authorization: Bearer <token>)
GET   /repos/:owner/:repo                              // default branch, permissions
GET   /repos/:owner/:repo/git/trees/:sha?recursive=1   // every path + blob sha
GET   /repos/:owner/:repo/git/blobs/:sha               // file content (base64)
GET   /repos/:owner/:repo/tarball/:ref                 // whole repo, for search
POST  /repos/:owner/:repo/git/blobs                    // commit step 1
POST  /repos/:owner/:repo/git/trees                    // step 2: base_tree + changed paths
POST  /repos/:owner/:repo/git/commits                  // step 3: tree + parent sha
PATCH /repos/:owner/:repo/git/refs/heads/:branch       // step 4: move the branch (fails if not fast-forward)

// Main thread <-> extension host
type ToExtHost =
  | { type: "documentOpened"; uri: Uri; languageId: string; version: number; text: string }
  | { type: "documentChanged"; uri: Uri; version: number; changes: { range: Range; text: string }[] }
  | { type: "documentClosed"; uri: Uri }
  | { type: "provide"; id: number; feature: "completion" | "hover" | "definition"; uri: Uri; position: Position }
  | { type: "executeCommand"; id: number; command: string; args: unknown[] }
  | { type: "cancel"; id: number };

type FromExtHost =
  | { type: "result"; id: number; value: unknown }
  | { type: "error"; id: number; code: number; message: string }
  | { type: "setMarkers"; uri: Uri; owner: string; version: number; markers: Marker[] }
  | { type: "registerCommand"; command: string }
  | { type: "fsRequest"; id: number; op: "stat" | "read" | "write" | "readDirectory"; uri: Uri; data?: Uint8Array };
The extension host never sends DOM operations. It sends data (markers, completion items, decorations by range) and the main thread decides how to draw it. That keeps the boundary narrow enough to version and to audit.
Offline
- App shell. A service worker precaches the versioned workbench bundle, CSS, fonts, and the core language workers on install. Navigation requests are served cache-first, so the IDE opens with no network.
- Updates. A new deploy installs a new service worker with a new cache name. Don’t call
skipWaiting()blindly in the middle of an edit session: show “Reload to update” so the workbench and its workers never run mixed versions. - Extensions. Cache installed extension bundles by version in the Cache API or OPFS, so an offline start still has your themes and languages.
- Files. Previously opened blobs come from OPFS. Unsaved edits come from IndexedDB backups. Commits to GitHub wait in the Source Control view until
navigator.onLineand a successful request say you are back.
Optimizations
| Problem | Technique | Effect |
|---|---|---|
| Edits copy the whole file | Piece tree with append-only add buffer | O(log n) per edit, no big strings |
| 100,000 lines of DOM | Virtualized lines with reused containers | ~50 lines in the DOM at any time |
| Re-highlighting the file on each edit | State-carrying tokenizer, stop when state matches | Usually one line re-tokenized |
| Extensions blocking input | Extension host in a worker | Typing never waits on extension code |
| Slow startup | Activation events, lazy language servers, code-split workbench | Cost scales with what you open |
| Large postMessage payloads | Deltas, transferables, MessageChannel | No full-document clones after open |
| Rate-limited repo browsing | One recursive tree call, sha-keyed blob cache | One request to list 20,000 files |
| Token objects and GC | Uint32Array per line | No per-token allocation |
Measure the keystroke path with the Event Timing API. Interaction to Next Paint (INP) on keydown and input events is the number that matches the 16ms budget, and a long-task observer on the main thread tells you which extension provider or tokenizer slice blew it.
Handling Edge Cases
- IME composition. Chinese, Japanese, and Korean input arrive through
compositionstart,compositionupdate, andcompositionend. Don’t send intermediate composition text to the language server or trigger completion until the composition ends. - Surrogate pairs and line endings. An emoji is two UTF-16 code units. Cursor movement must step over both, and LSP positions must count both. Keep the file’s original line ending (LF or CRLF) and normalize only inside the buffer.
- Huge single-line files. A 5 MB minified bundle is one line. Skip tokenizing lines beyond a length limit (Monaco’s
editor.maxTokenizationLineLength), stop rendering after a character cap, and turn off folding and the minimap for very large files. - Binary files. Detect NUL bytes and show a binary or image preview instead of loading them into a text model.
- Changed on GitHub while you edit. The ref update on commit fails. Fetch the new head, show a diff of your changes against it, and let the user rebase or commit to a new branch.
- Changed on disk while you edit. On focus, a newer
lastModifiedwith a clean model reloads silently. With a dirty model, show a compare view instead of choosing for the user. - Lost folder permission. After a reload, the stored handle needs
requestPermission, which needs a click. Show a “Reopen folder” button instead of an empty explorer. - Extension host crash. Catch the worker’s
errorevent, restart it, resenddocumentOpenedfor open models, and tell the user which extension was active. Keep the editor fully usable without it. - Storage eviction. If
persist()is denied, warn before a session holds many unsaved files, and checknavigator.storage.estimate()before unpacking a large archive.
Accessibility and Security
Accessibility
A screen reader cannot read a virtualized DOM of colored spans. Monaco solves this with the same hidden <textarea> that captures input. In screen reader mode, the textarea contains the text around the cursor (the current line, or a page of lines), with its selection set to match the editor selection. The screen reader reads a real text field, and arrow keys announce the line or character you move to.
- Browsers don’t tell a page that a screen reader is running, so screen reader mode is a setting. The textarea’s accessible label tells users how to reach it (Monaco announces “Press Alt+F1 for Accessibility Options”).
- Every feature is reachable by keyboard, and the command palette is the fallback for anything without a binding. Ctrl+M (Ctrl+Shift+M on macOS) toggles whether Tab inserts a tab or moves focus, so keyboard users can leave the editor.
- Diagnostics and completion changes are announced through ARIA live regions. The Problems panel is a navigable list, and F8 jumps to the next error.
- Ship high contrast dark and light themes, and switch to them when the OS reports
forced-colors: active. Never encode meaning in color alone: errors have squiggles and icons, not only red. - Honor zoom and font size settings without breaking line height math, and respect
prefers-reduced-motionfor smooth scrolling and cursor animation.
Security
- GitHub tokens. Use OAuth with the narrowest scopes needed. Keep the token in the workbench, never in the extension host’s reach, and have the GitHub provider request it through an authentication API that asks the user per extension. Never put it in a URL or log.
- Webview origin isolation. Each webview runs on a separate origin from the workbench, with a CSP that blocks inline scripts unless the extension uses a nonce. Messages from a webview are validated before acting on them.
- Restricted Mode. A workspace from an unknown repository opens untrusted. Extensions whose manifest says
untrustedWorkspaces.supported: falseare disabled, and"limited"ones turn off risky features. Workspace settings that point to executables or scripts are ignored until the user trusts the folder. - Rendering file content. File text, file names, hover Markdown, and commit messages are all untrusted. Escape everything in the line renderer, and sanitize rendered Markdown with a strict allow list.
- Extension supply chain. Install only from a marketplace that signs packages, verify the signature before loading, and serve bundles from a dedicated origin listed in the CSP.
What a Strong Answer Sounds Like
| Topic | Junior answer | Senior answer |
|---|---|---|
| Text buffer | A string in React state | Piece tree with cached length and line feed counts |
| Rendering | A <textarea> with a highlight overlay |
Virtualized lines, separate cursor layers, hidden textarea for input |
| Highlighting | Regex the whole file after each keystroke | State-carrying tokenizer that stops when the end state matches |
| Extensions | Load plugins as scripts on the page | Worker extension host, RPC, activation events, webviews on their own origin |
| Language features | Call an API for errors | LSP in a worker, incremental didChange, cancellation, versioned diagnostics |
| Files | Fetch each file from GitHub | Provider per scheme, one tree call, sha-keyed cache, batched commits |
Conclusion: How to Design VS Code for the Web
Start with the 16ms rule: the keystroke updates a piece tree, re-tokenizes one line, and repaints a virtualized view, all on the main thread and all before anything else happens. Everything that can be slow, extensions, language servers, search, runs in Web Workers behind a cancellable RPC boundary.
Then abstract the outside world. Files are URIs routed to providers, so GitHub, a local folder, and an offline cache look the same to the editor. Language intelligence is LSP messages with versions, so stale answers are easy to drop. If you can explain why the tokenizer stops when the end state matches and why didChange is never debounced, you’ve shown the interviewer you understand how a real code editor works.