
Design an Observability Dashboard – Frontend System Design
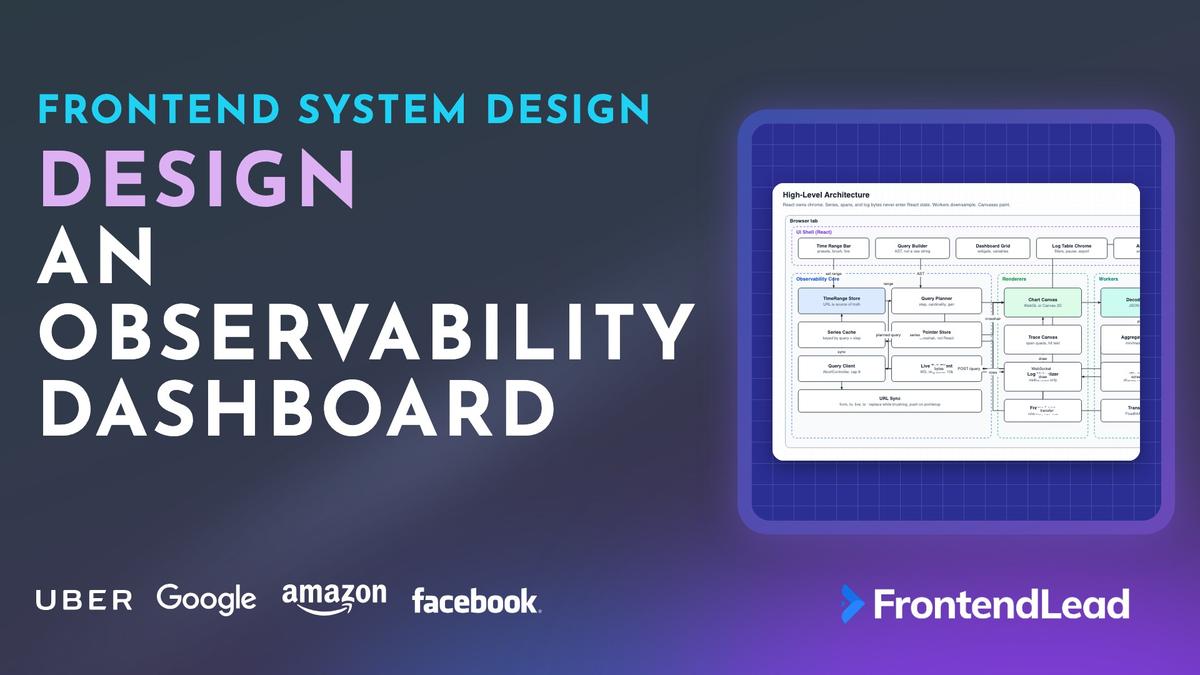
We’ll walk through the frontend system design for an observability dashboard like Datadog or Grafana: a page of linked charts, a query builder that can explode into a million series, a live log tail, and a trace waterfall that has to stay at 60fps. You’ll see why the time range lives in a store backed by the URL, why the client never plots more points than the screen has pixels, how a worker turns a fat query response into a pair of typed arrays, and why a span is a WebGL quad instead of a DOM node.
This is not the data table question, and it is not “put Chart.js in a grid.” A table of 10,000 rows is virtualization. A dashboard that fans one brush out to twenty high-cardinality widgets is a data-volume problem. The interviewer is asking whether you can keep React off the hot path.
Problem Statement
Design the frontend for a metrics, traces, and logs dashboard used by on-call engineers.
Requirements:
- A grid of charts that share one time range, including brush-to-zoom
- A query builder with filters, aggregators, and group-by, over high-cardinality metrics
- Time series that stay smooth while the user zooms from seven days down to thirty seconds
- A trace waterfall / flame graph for a single request with tens of thousands of spans
- A virtualized log table and a live tail that can survive a burst
- A URL that captures the time range so a teammate can open the same view
Describe the client architecture, the series model, how you downsample on zoom, and how workers and canvases keep the main thread free.
Interviewers are checking three things. Do you treat series data as bytes and typed arrays, not as React state? Can you explain level-of-detail for time, the same way a maps answer explains a tile pyramid? And do you know that average-only downsample hides the incident you opened the page to find?
Clarifying Questions
| # | Question | Interviewer’s Answer |
|---|---|---|
| 1 | Who is this for, and what do they do with it? | On-call engineers. They scan a service dashboard, zoom into a blip, jump to traces, then tail logs. |
| 2 | How wide is a typical dashboard, and how hot is a query? | 10–30 widgets. A widget may group by host or endpoint and return 50–500 series. A bad group-by can request tens of thousands. |
| 3 | What time windows matter? | Presets from 15 minutes to 7 days. Live mode on the short windows. Custom brush down to a few seconds. |
| 4 | Metrics, traces, and logs on day one? | Yes. Metrics are the default landing page. Traces and logs open from a point on a chart or from a search. |
| 5 | Who owns rollups, the client or the server? | The time-series database already stores 10s / 1m / 5m / 1h rollups. The client picks a step and may shrink further to the screen. |
| 6 | Shareable link, or live presence? | Shareable URL. Two people can open the same link and then wander independently. |
Question 2 is the cardinality question. If you skip it, you will design for 8 series and the first production dashboard will freeze the tab. Question 5 tells you not to invent a client-side TSDB. Question 3 decides the URL scheme: relative ranges (now-1h) for live mode, absolute timestamps after a brush.
Requirements
Functional
- Dashboard grid of timeseries, heatmaps, stats, a trace waterfall, and a log table.
- Shared time range: presets, from/to, brush-to-zoom, and live mode with a visible pause.
- Query builder: metric, tag filters, aggregator, group-by, functions, and a series limit.
- Click a point or span and pivot to related traces, logs, or a filtered query.
- Virtualized logs with filters, search, and a live tail that can pause.
- Shareable URL for time range, live flag, timezone, and dashboard variables.
Non-Functional
- 60fps while brushing, hovering a crosshair, or scrolling logs, on a mid-range laptop.
- A range change paints something useful in under 300ms from cache, and under 2s from the network on a warm query.
- Memory bounded: series buffers, log ring, and GPU geometry have caps and an eviction policy.
- A bad group-by cannot take the tab down. Warn, cap, or refuse before you fetch.
- Keyboard access to the time bar, query builder, and log table. Charts have a text alternative.
60fps is a 16.7ms budget. Decoding 3 million points, reconciling 20 React subtrees, and stroking 50 Canvas paths on the same frame will miss it. The whole design is about moving that work off the frame, or not doing it at all.
Napkin Math
| Metric | Estimate | Calculation | So what? |
|---|---|---|---|
| 7 days at 10s | 60,480 pts / series | 7 × 24 × 360 | Never fetch this for a 1,200px chart. |
| 50 series, raw 10s, 7d | ~48 MB | 3.02e6 × 16 bytes (t, v) | One widget, already a GC problem. |
| Same 50 series, screen LOD | ~1.9 MB | 1,200px × 2 pts × 50 × 16 | This is what the canvas should hold. |
| 20 widgets × 3 queries | 60 in-flight | One range change, no cap | Cap concurrency at ~8 and queue. |
| Live tail burst | 2.4 MB/s | 6,000 lines/s × 400 B | A ring of 10k lines is 4 MB, not unbounded. |
| Fat trace | ~1.3 MB draw data | 40,000 spans × 32 B | Fine as quads. Fatal as DOM nodes. |
| Frame budget | 16.7 ms | 1000 / 60 | Leave ~8 ms for input and React chrome. |
Architecture

The client has four layers, and the most important decision is which one is allowed to hold points.
| Layer | Owns | Runs on | Talks to |
|---|---|---|---|
| UI Shell | Time bar, query builder, grid, log chrome | React, main thread | Sends intents, reads derived summaries |
| Observability Core | Time range, query plan, series cache, pointer | TypeScript, main thread | Workers, query client, URL sync |
| Renderers | Chart canvas, trace canvas, log virtualizer | WebGL / Canvas 2D / DOM window | Reads typed arrays, not React props |
| Workers | Decode, min/max, LTTB, histogram merge | Worker pool | Transferable ArrayBuffers |
React renders the chrome. It does not store time series. A range change updates a store, bumps a generation, plans a step, and asks the query client for bytes. A worker turns those bytes into Float64Arrays sized for the screen. One requestAnimationFrame loop draws. Legends sample the cache a few times a second.
“React owns the form controls. The series live in typed arrays behind a cache keyed by query, step, and generation. If a point is in
useState, the design is already wrong.”
Why not one chart library per widget?
| Approach | Good at | Breaks at |
|---|---|---|
| SVG / DOM marks | Pretty tooltips, CSS | A few thousand points: layout per mark |
| Chart.js in React state | A marketing dashboard | Linked zoom, 500 series, live appends |
| Canvas 2D, shared store | Tens of series, hover, brush | Heatmaps and 40k-span traces |
| WebGL / WebGPU | Heatmaps, traces, many series | You build hit testing and text yourself |
Ship Canvas 2D for ordinary timeseries. Move heatmaps and traces to WebGL. The senior point is the boundary, not the GPU API. Same idea as the Figma canvas and the map tile pyramid: the framework does not paint the hot view.
Data Model

There is one shared TimeRange. Every widget reads it. None of them own it. Queries are an AST, not a raw PromQL string that you regex. Series are typed arrays. Logs and spans are separate types because they have different cardinality and different renderers.
type RelativeExpr = `now-${string}`; // "now-15m" | "now-1h" | "now-7d"

interface TimeRange {
  from: number | RelativeExpr; // epoch ms, or relative to "now"
  to: number | "now";
  live: boolean;
  tz: string;
  resolutionMs: number;        // planned step, not a guess at draw time
}

type FilterOp = "=" | "!=" | "=~" | "!~";

interface Filter {
  key: string;
  op: FilterOp;
  value: string;
}

interface Query {
  id: string;
  metric: string;
  filters: Filter[];
  aggregator: "sum" | "avg" | "min" | "max" | "p50" | "p99";
  groupBy: string[];
  functions: Array<{ name: "rate" | "increase" | "histogram_quantile"; args: number[] }>;
  limit: number;               // hard cap on series, default 200
}

interface Series {
  queryId: string;
  tags: ReadonlyMap<string, string>;
  stepMs: number;
  times: Float64Array;
  values: Float64Array;
  mins?: Float64Array;         // envelope, same length as values
  maxs?: Float64Array;
  generation: number;
}
Four choices in that model are worth defending.
One time range, not one per widget. Linked charts are a feature, not a coincidence. A brush writes the store. Every subscriber plans a new step and refetches. A widget that needs a different window (compare to last week) stores an offset against the shared range, not a private copy that drifts.
An AST, not a string. Autocomplete, cost estimates, and variables ($env, $service) are tree edits. You serialize to PromQL or Datadog query language at the wire. If the source of truth is a string, every keystroke is a parse, and a bad paste becomes an injection footgun.
Typed arrays with a generation. The worker transfers the buffers. The cache keeps the previous generation on screen until the new one arrives, so zoom does not flash empty. A late response whose generation no longer matches is dropped.
A series limit on the query. Group-by path on an HTTP metric is how you ask for 80,000 series. The builder shows an estimated cardinality. Above query.limit, the query does not fire until the engineer adds a filter or top-k.
Spans and log events stay out of the series cache. A span is a packed row for the trace canvas. A log event is a row in the virtualizer’s ring. One “event” union looks tidy and makes every hot path branch.
Time Series and Downsampling

The screen is the budget. A 1,200px chart cannot show 60,000 distinct x positions. Fetching them so the client can throw them away is how dashboards miss frames. Treat time like a tile pyramid: pick a step from the window and the width, ask the server for that rollup, then shrink once more in a worker so the canvas holds about two points per CSS pixel.
The step planner is a pure function of the window and the chart width. It divides the window by the pixel budget (width times about two points per pixel) to get the smallest step that fits, then rounds up to the nearest rollup the TSDB actually stores: 1s, 10s, 1m, 5m, or 1h. A window larger than the coarsest rollup can serve still uses the coarsest one.
| Window at 1,200px | Smallest step that fits | Rollup used | Points before the worker |
|---|---|---|---|
| 7 days | ~252 s | 5m | ~2,016 |
| 1 hour | ~1.5 s | 10s | ~360 |
| 5 minutes | ~125 ms | 1s | ~300 |
Two shrinks, two jobs.
Server rollup. The TSDB already merged raw samples into 10s / 1m / 5m / 1h buckets. You ask for a step it has. You do not download seven days of 10s data and average it in JS. That is the client pretending to be a database.
Client shrink. Even a well-chosen rollup can be larger than the screen (a 5m step over 7 days is still ~2,000 points). The worker builds a min/max envelope per screen column, then runs Largest-Triangle-Three-Buckets on the midline so the line still looks like the raw shape.
Average-only downsample is the junior trap. A 30-second CPU sit at 100% falls inside a one-hour average and becomes a 2% bump, or nothing. On-call charts exist to show outliers. Keep the envelope. LTTB the midline. If you only have time for one sentence, say that.
Zoom is a new query, not a CSS scale
Scaling last hour’s 10s series up to fill a 5-minute brush looks like a step function and lies about peaks you never fetched. On commit, plan a finer step, abort the in-flight request, increment generation, and fetch. While you wait, keep the old series on screen at the new camera, maybe dimmed, the same way a map shows a scaled parent tile until the child arrives.
The series loader owns a global generation counter and one AbortController per query. A load does five things in order:
- Increment the generation and remember its own value.
- Plan the step from the resolved window and the chart width.
- Abort any in-flight request for the same query, then fetch the new one.
- When bytes arrive, drop them if a newer generation exists. Otherwise send them to the worker pool to downsample.
- When the screen series comes back, check the generation again, store it in the series cache, and invalidate that chart’s frame.
The two generation checks are the design. Without them, a slow 7-day response lands on top of the 5-minute window the engineer is staring at, then the 5-minute response lands, and the chart flickers through the wrong incident.
Live mode is the same pipeline on a timer. Every 10s, to is now and from slides. Do not append one raw sample at a time onto a 7-day series. Re-plan. For a 15-minute live window you can append into a ring and drop the points that have scrolled off the left edge.
Query Builder
The builder is a structured editor over the AST. Metric name first, then filters, then aggregator and group-by, then functions. Each field has typeahead from GET /suggest/metrics and GET /suggest/tags?metric=&key=.
- Debounce typeahead ~200ms and cancel the previous suggest request.
- Show estimated series count next to group-by. Refuse to run above
query.limit(200 default, 500 ceiling). - Resolve variables (
$env) in the core before serialize so every widget binds the same values. - The open builder is React. The running query is a frozen AST. Editing does not mutate the screen until Apply.
The serializer is a pure function from the AST and the resolved variables to a PromQL string. It strips the metric name to legal characters, resolves each filter value’s variables, escapes the value as a quoted label string, and joins filters with commas. Group-by becomes a by (...) clause, and the aggregator wraps the selector. No part of the output is ever raw user text.
Sanitize at serialize time. Never interpolate a raw token into a string. The server still ACL-checks the query; the client check is for the tab, not for security.
A raw PromQL panel is an escape hatch. Parse it back into an AST when you can, and keep the raw text when you cannot, so a round-trip does not rewrite the query.
Linked Charts and URL State

Brush, presets, and the from/to fields all write the same store. Widgets subscribe. The URL is the durable copy, not a second source that widgets parse in render.
// /dash/payments?from=now-1h&to=now&live=1&tz=America/Los_Angeles&env=prod
// after a brush:
// /dash/payments?from=1698760123000&to=1698760423000&live=0&tz=America/Los_Angeles&env=prod
The URL holds the range (relative expression or absolute epoch ms), the live flag, the timezone, and every template variable as a flat query param. One function maps the store to those params, and one maps them back on load.
Three rules keep this from fighting the browser.
Replace while dragging, push on pointerup. A brush generates dozens of pointer events. history.pushState on each one makes Back a walk through every pixel of the drag. replaceState during the gesture, pushState when the range commits. Presets and the picker always push.
Resolve relative ranges at the edge. Store now-1h until someone brushes. Then persist absolute ms, and turn live off. If you rewrite now-1h to timestamps on every load, a shared link stops meaning “the last hour” the moment you copy it.
Do not put twenty query strings in the URL. The dashboard JSON already has the widgets. The URL holds range, live, timezone, and template variables. If you need a one-off override, compress one widget’s AST into a single param, or mint a short snapshot id. A 4 KB query string will be the first thing a proxy truncates.
The crosshair is not the time range. Hovering should line up every chart at the same timestamp without refetching and without writing the URL. That is a pointer store updated from the canvas pointermove, read by the other canvases in the same frame. Putting it in React is how a hover drops to 20fps.
Back and Forward rehydrate the store from popstate and take the same generation path as a brush. The URL is how the page loads, not a side effect you fire and forget.
Traces on a Canvas
A trace with 40,000 spans is a scene, not a list. A DOM node per span means 40,000 layout boxes, 40,000 hit regions, and a style recalc when you hover. Draw spans as colored quads. Keep a packed buffer. Hit-test it yourself.
interface SpanQuad {
  x: number;       // start, in trace-local ms
  w: number;       // duration ms
  depth: number;   // row
  color: number;   // service palette index
  spanIndex: number;
}
The span hit tester converts the pointer x to trace time with the camera, and the pointer y plus scroll offset to a depth row. It then looks only at spans in that row whose time range contains the pointer and returns the narrowest one, because a child span sits inside its parent’s range and the user meant the most specific thing under the cursor.
A linear scan over one depth is cheap: tens or hundreds of spans, not 40,000. If the interviewer pushes, sort each depth by start time and binary-search. GPU picking is exact and stalls on readPixels; mention it as a fallback. Same trade-off as Figma’s R-tree versus GPU pick.
Zoom toward the cursor by keeping the timestamp under the pointer fixed. A minimap shows the whole trace. Clicking a span sends a selection id into React; the details panel fetches attributes if they were stripped from the draw path. Waterfall and flame graph are two projections of the same buffer. Rebuild the quad list in a worker. Do not rebuild a React tree to switch.
Logs, Live Tail, Virtualization
Search is paged. Tail is a stream. Do not implement tail by polling search every second. The search API returns a cursor. The live gateway opens a WebSocket (SSE if a proxy eats WS) with the same filter AST.
The tail buffer is a fixed array of 10,000 slots with a head index, a length, a paused flag, and a dropped counter. Each batch from the socket is written at the tail. Once the buffer is full, every write advances the head and overwrites the oldest line. While paused, the batch is not stored, and only the dropped count grows. After each batch the log view is invalidated, and the virtualizer reads whatever rows are visible straight from the ring.
Three rules keep a burst from melting the tab.
Ring buffer, not an array you unshift. Ten thousand lines at 400 bytes is 4 MB. An unbounded array at 6,000 lines/s is 2.4 MB/s and a crash. When the ring wraps, the oldest line is gone. Show that.
Pause when the user scrolls up. Tail is a viewport stuck to the bottom. The moment they scroll to read a stack, you stop appending into the visible window. A banner says how many lines were skipped. Resume jumps to the live edge. Datadog and CloudWatch both do this because the alternative is fighting the scrollbar.
Sample at the gateway when ingress exceeds what you can paint. If the worker or the virtualizer is behind, ask the socket for 1-in-N and show “showing 1 of 12.” Dropping on the client after you have already parsed 6,000 JSON objects is too late.
The table is a virtualizer: about 30 mounted rows, cached heights for wrap, sticky header, frozen timestamp. Render messages as text, never through innerHTML. Log lines are untrusted. Linkify traceId with a click handler. Following a span is a store write: add the filter, pad the span’s window, let the URL update so Back works.
Worker Aggregation

JSON.parse of a 3 million point payload on the main thread is a dropped frame you can measure. Do it in a worker. Shrink there too. Transfer the result. The main thread should see a handful of Float64Arrays, not a tree of objects.
The worker contract is one message in and one message out. In: the generation, the chart width, the step, and the raw payload as an ArrayBuffer in the transfer list, so the main thread gives it up instead of copying it. Out: the same generation and, for each series, four typed arrays (times, values, mins, maxs), also transferred. Inside, the worker decodes the payload and shrinks each series to the screen with the envelope plus LTTB. The generation goes along for the round trip, so the main thread can drop a stale result without asking the worker which job it was.
One pool for the tab, not one worker per widget. Cap inflight jobs at eight. If the pool is behind, drop the oldest raw payload for that query and keep the last screen series. Heatmaps merge by adding bucket counts in the worker. Use requestAnimationFrame only to draw. The teleoperation dashboard makes the same split for 50 Hz telemetry: workers and ring buffers, React for labels.
API
REST or gRPC-web for request/response. One WebSocket (or SSE) for live tail. Do not put metric polls on the tail socket. They have different fan-out, different ACLs, and different backpressure.
// REST
POST /api/metrics/query
  body: { queries: Query[]; from: number; to: number; stepMs: number }
  -> { generationHint?: number; series: EncodedSeries[] }   // protobuf preferred

GET  /api/suggest/metrics?q=
GET  /api/suggest/tags?metric=&key=&q=
GET  /api/metrics/cardinality?query=                        // estimated series count

GET  /api/traces?service=&from=&to=&minDurationMs=
GET  /api/traces/:traceId
GET  /api/logs/search?from=&to=&cursor=&filter=

GET  /api/dashboards/:id
PUT  /api/dashboards/:id                                    // layout + widget ASTs

// WebSocket: wss://tail.example.com/logs
type TailClient = { type: "subscribe"; filter: Filter[]; since: number; sample?: number };
type TailServer = { type: "batch"; events: LogEvent[] } | { type: "overflow"; dropped: number };
Prefer protobuf or a columnar encoding. JSON for 500 series of 2,000 points is a multi-megabyte parse. If the API is JSON, still fetch as an ArrayBuffer and parse in the worker. POST /query so a 30-widget dashboard does not blow the URL. Cap client concurrency at eight. On 429 or 503, keep the last series and back off that widget. On a cardinality error, show the estimate on the widget that caused it.
Optimizations
| Problem | Technique | Effect |
|---|---|---|
| 3M points on the main thread | Worker decode + Transferables | Main thread sees screen-sized arrays |
| Zoom refetch storm | generation + AbortController + cap 8 | Late payloads cannot paint |
| Average hides incidents | min/max envelope + LTTB midline | Peaks stay visible |
| Hover at 60Hz | Pointer store, not React state | Crosshair does not reconcile the tree |
| 20 chart libraries | One frame loop, shared GPU context | One rAF, not twenty |
| 40k-span traces | WebGL quads + row hit test | No DOM per span |
| 6k logs/s | Ring + pause + gateway sample | Memory and DOM stay flat |
| Group-by explosion | Cardinality estimate + query.limit | The tab never fetches 80k series |
Cache series by (queryId, stepMs, from, to). A brush that is a subset of a fetched window can clip in the worker if the step is already fine enough. If the step is too coarse, refetch. Do not fake resolution you do not have. Prefetch the next preset on hover.
Handling Edge Cases
- Clock skew. Clamp
totonow + 2m. Do not let live mode chase a 4-hour-fast host into an empty window. - Partial widget failure. One 500 cannot blank the grid. Each widget keeps its last-good series and its own error.
- Gaps are not zeros. A missing scrape should break the path, not draw through 0 and page someone.
- DST. Store UTC ms. Render ticks in
TimeRange.tz. Label in UTC too when the window crosses a fold. - WebGL context loss. Rebuild from the CPU buffer. The buffer is the source of truth.
- Hidden tab. Pause live polls and tail. Resume with a fresh range, not a burst of backlog.
- Tail disconnect. Re-subscribe with
since = lastTs. If the gateway cannot replay, show a gap, not a silent skip.
Accessibility and Security
Accessibility
A canvas is one bitmap to a screen reader. Make the chrome usable and give each chart a text alternative.
- Time bar, query builder, variables, and log table are real labeled controls. Presets are a listbox. Brush has a from/to keyboard equivalent.
- Each chart exposes the query, latest value, min/max, and a toggle to a virtualized table of the screen series.
- Do not encode series identity with color alone. Dash patterns and legend labels matter on-call.
- Announce range commits in
aria-live="polite". Do not announce the crosshair. Honorprefers-reduced-motion.
Security
- Every query is ACL-checked on the server. Hiding a widget is not an ACL.
- Log messages and span names are untrusted text. A payload like
<img src=x onerror=…>is a support ticket, not markup. - Serialize the AST. Do not concatenate tokens into PromQL.
- Shared links carry range and variables, not a bearer token. Tail sockets inherit the session.
What a Strong Answer Sounds Like
| Topic | Junior answer | Senior answer |
|---|---|---|
| Charts | “Use Chart.js in React” | Shared store, canvas or WebGL, one rAF, series as typed arrays |
| Zoom | Scale the existing line | Plan a step, fetch that rollup, keep stale series, drop old generations |
| Downsample | Take every Nth point | Min/max envelope so spikes survive, LTTB for the midline |
| Linked charts | Context on every mouse move | TimeRange store + URL; crosshair is a separate pointer store |
| Traces | A div per span | Packed quads, row hit test, details panel is a selection id |
| Live tail | setState per line | Ring buffer, virtualizer, pause on scroll, sample at the gateway |
| Workers | “Maybe a worker” | Shared pool, Transferables, drop raw payloads when behind |
Conclusion: How to Design an Observability Dashboard
Start with the boundary: React for the chrome, a store for the time range, typed arrays for series, and a canvas for anything that moves at 60Hz. Plan a step from the window and the width, fetch the rollup the database already has, and shrink once more in a worker so the screen holds about two points per pixel, with a min/max envelope so a spike cannot vanish into an average.
That one decision pays off everywhere. Linked charts are subscribers to one range. The URL is how that range survives a refresh and a Slack paste. Traces are the same idea with spans instead of points. Logs are a ring and a virtualizer, not a growing React list. If you can explain the generation check on a late zoom response and why average-only downsample hides incidents, you have shown the interviewer you have used one of these tools during an outage, not just imported a chart package.